Author: Betre Tezera
-
Benchmarking Machine Learning for Basketball Performance
A recent study published in Knowledge and Information Systems shows us an analysis of machine learning (ML) models for predicting the future performance of basketball players. This study tested 14 different ML models against 18 basketball statistics and Key Performance Indicators (KPIs).
Methodology and Data Focus
The researchers applied their methodology to a pool of 90 NBA players. To qualify, players had to meet strict criteria based on high averages across crucial KPIs like GameScore (GMSC), FOUR FACTORS, TENDEX, Fantasy Points (FP), and Efficiency (EFF) and the players had to have had a good amount of participation time (15+ minutes) over three recent seasons (2019–20 up to 2021–22).
The study focused on developing individual scenarios for each player and the players averages in their past games in order to predict upcoming games. The 14 ML models tested spanned several categories, including Linear-Based models, Tree-based models, Non-Parametric (K-nearest neighbors or KNN), and Online-Learning models. To keep it simple, the study used different versions of models that best suit the measuring category.
In order to rank the models in comparison to each other, the authors made an evaluation metric called the weighted average percentage error (WAPE), which is derived from the weighted Mean Absolute Percentage Error (MAPE) results for each statistic and model.
Key Findings: Tree-Based Models Dominate
The research clearly showed that the Tree-based models are the best performers across most of the tested performance indicators.
The best models, based on performance against unseen data, were ranked as follows by WAPE score:
- Extra Trees (ET): Achieved the best performance with a WAPE of 34.14%. ET was a better predictor for metrics such as AST RATIO, PIE, PM, and TOV.
- Random Forest (RF): Scored a WAPE of 34.23%.
- Decision Tree (DT): Scored a WAPE of 34.41%.
While Tree-based models were really good, certain Linear-Based models like LASSO (34.54% WAPE) and LARS (34.53% WAPE) also showed exceptional overall performance, demonstrating good accuracy for specific metrics.
Optimizing KPI Forecasting
A crucial finding of the study was the success of a comprehensive forecasting approach designed to improve KPI prediction results, specifically focusing on Fantasy Points (FP).
Instead of forecasting FP as a single combined metric, the researchers experimented with forecasting the six constituent individual metrics (Points, Rebounds, Assists, Steals, Blocks, and Turnovers) separately, and then constructing the FP KPI from these predictions.
This optimized approach led to a significant improvement. The overall forecasting accuracy for FP improved by 3.6% MAPE on unseen data when utilizing this method. The Gradient Boosting Machine (GBM) model, for instance, achieved a MAPE of 29.81% when using the reformatted approach, which outperformed the best result from the single-metric forecast approach (LARS at 33.39% MAPE).
Implications
The findings show us lots of new insights for the sports analytics industry, including researchers, coaches, data scientists, and organizations that invest in creating data science departments for scouting insights. The research not only benchmarks current ML model performance but also introduces an innovative approach to improve KPI forecasting accuracy, showing us that advanced statistical techniques combined with practical methods can set a new benchmark for predicting professional basketball player performance. Future work suggested by the authors includes incorporating external factors such as sentiment analysis, betting odds, and motion capture data to further refine predictions.
What does this mean for the future of sports?
We are heading towards a future where statistical analysis can help teams attract the best talent and retain the best evaluate performers. The benchmarks are only getting better and more accurate. This begs the question of whether this is fair or not? Would it be fair for a team to cut a players contract based on data from a machine learning model? As these models start becoming more and more involved in team environments, the ethical considerations of using these models are going to start taking effect as well. So, what do you think; do you think these models are doing more good than bad for sports?
Reference
Papageorgiou, G., Sarlis, V., & Tjortjis, C. (2024). Evaluating the effectiveness of machine learning models for performance forecasting in basketball: a comparative study. Knowledge and Information Systems, 66, 4333–4375. https://doi.org/10.1007/s10115-024-02092-9 -
My Challenges with AI
My Challenges with AI
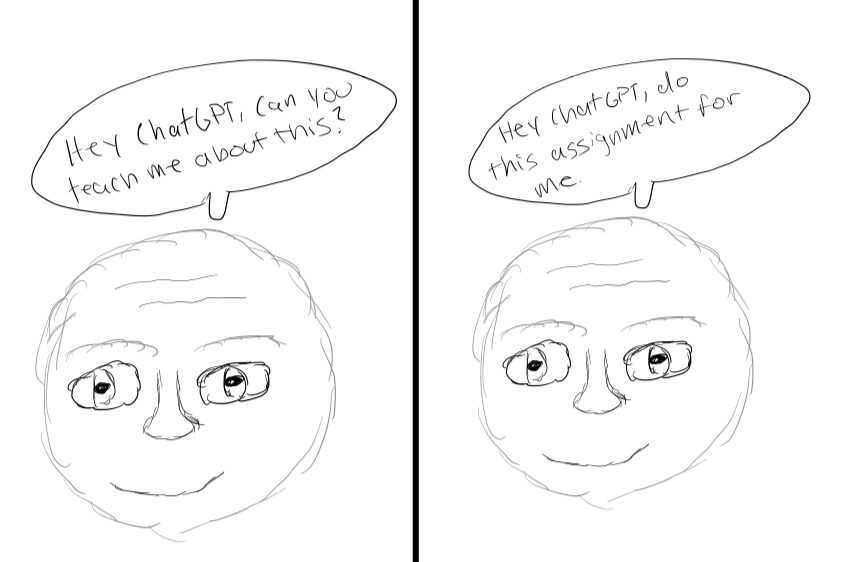
AI has taken over the world of technology; from software developers to artists, AI has an effect on almost all of us these days. In this essay I will be talking about the effects AI had on me as a college student and weigh out the good, the bad and the ugly.
The Good
Starting off with the good. AI has immensely aided in my understanding of various subjects from Computer Architecture (CS 2200) to understanding the Psychology of Cybersecurity (CS 4263). Whenever I am stuck, I see AI as an instant solution towards understanding the topic that I am having trouble with. Instead of having to wait for answers of Piazza or Ed discussion, or wait in lines at office hours, I am able to head over to an AI chatbot and get my answers instantly. Now you may be wondering, what if the answers are wrong? Well to limit this I give the AI the correct context. For example, if I am studying for a quiz for a math course, I would give the AI the correct lecture slides, textbook, study guide, etc. and then ask it questions based on the material. This strategy is especially useful with LLMs such as Notebook LM because it will only give you answers based on the text that you give it and no outside sources (unless you prompt it to use outside sources). AI also gives me the ability to really dig deep into a topic by asking it questions until I get a thorough understanding. This is especially beneficial in classes where office hours are usually crowded and you are not able to have too much time with the TA. The AI can serve as your substitute TA.
The Bad
Now, although these use cases help in bettering my education, there are many use cases where AI has done the opposite. The rise of AI in the past 3 years has caused many professors to begin to integrate it within courses. The professors understand the inevitability of AI usage by students in these courses, so they arrange for it to be available to students, but with various restrictions. One of the most common restrictions is copy and paste. Copying and pasting content from an LLM to an IDE or to wherever your workspace is, is almost always a violation in many courses. Having this type of tool freely available to students is very dangerous when it comes to our education. It is very easy and tempting for students to simply finish the assignment using AI. It is like having all the answers to the test, but you force yourself to not take a lot before going into the test. Although the restrictions help, they only do so much in restricting AI usage. In my personal experience, AI usage has done more good than harm for my education, but there are definitely instances (especially in essay writing) where I used AI to accelerate my writing process.
The Ugly
That was the bad part of AI, now let’s get into the ugly. The ugly part of AI usage is essentially a more extreme use of what I stated in the bad. AI use in the wrong students’ hands can be extremely detrimental to their education. From my personal experience as a student I can completely see how someone can get through all 4 years in college without learning a thing and simply just using AI. Especially with the larger tokenized models that continue to release every few months, I speculate that in less than a year (unless colleges find extreme AI detection resources) there are going to be many students that can achieve their whole degree with just AI.
To sum up my position through my anecdotal experience, I would say that the benefits of and detriments of AI all depend on the person using it. If someone wants to better their education by using AI as a partner to learn then they would benefit tremendously, but if one simply uses AI as a tool to complete all of their assignments then they would reap the detriments of AI usage.
-
Macroevolution: The Big Picture of Life’s Changes
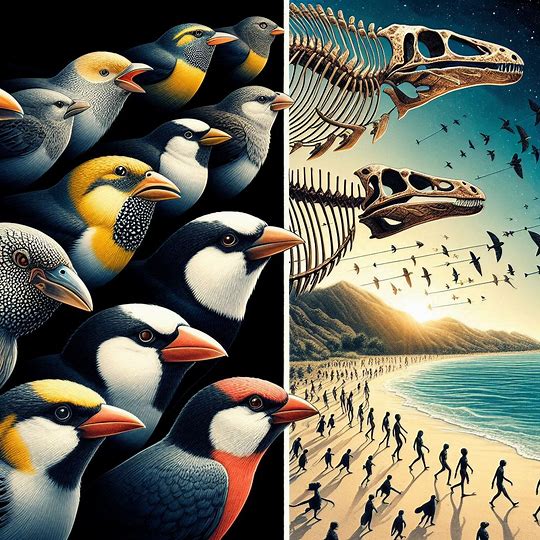
When most people think about evolution, they picture small changes happening over time, like finches developing different beak shapes or bacteria becoming resistant to antibiotics. But there’s actually a much bigger story happening on a grander scale, and that’s what macroevolution is all about. While microevolution deals with those small, observable changes within species, macroevolution zooms out to look at the really major transformations: how new species emerge, how entire groups of organisms come to be, and how life on Earth has diversified into the incredible variety we see today.
So what exactly counts as macroevolution? Basically, it’s evolutionary change that happens at or above the species level. We’re talking about the origin of new species (speciation), the emergence of major new body plans and features, and patterns we can see when we look at the fossil record over millions of years (Futuyma, 2017). Think about how different a whale is from its land-dwelling ancestors, or how birds evolved from dinosaurs. Those are macroevolutionary changes. These transformations don’t happen overnight; they accumulate over vast stretches of time through the same basic mechanisms that drive microevolution, just playing out on a much larger scale.
One of the coolest things about macroevolution is how we can actually track it through multiple lines of evidence. The fossil record is probably the most obvious one. It literally shows us snapshots of life from different time periods, and we can see how organisms have changed over millions of years. We can observe transitional fossils, like Tiktaalik, which shows features of both fish and early tetrapods, giving us insight into how vertebrates made the move from water to land (Shubin et al., 2006). But fossils aren’t the only evidence. Comparative anatomy reveals how different species share similar structures because they inherited them from common ancestors. The bones in a human arm, a bat’s wing, and a whale’s flipper are arranged in basically the same way, which makes sense when you realize we all share a common ancestor.
Then there’s molecular evidence, which has become huge in recent decades. By comparing DNA sequences between different species, scientists can reconstruct evolutionary relationships and even estimate when different lineages split apart. The more similar the DNA, the more recently two species shared a common ancestor (Bromham, 2016). This molecular data often confirms what we suspected from fossils and anatomy, but sometimes it reveals surprising connections we didn’t know about.
What drives these large-scale changes? A lot of it comes down to the same processes that cause microevolution (natural selection, genetic drift, mutation, and gene flow) just operating over much longer time periods. But there are also some big-picture factors at play. Mass extinctions, for instance, have dramatically reshaped life on Earth multiple times, wiping out dominant groups and creating opportunities for survivors to diversify into newly available ecological niches. Geographic isolation also plays a major role in speciation. When populations get separated by mountains, oceans, or other barriers, they evolve independently and can eventually become different species.
Some people try to draw a hard line between micro and macroevolution, but most biologists see them as the same processes just viewed at different scales. The small changes we can observe in real time, given enough time and the right circumstances, can accumulate into the major transformations we see in the fossil record. It’s like the difference between watching a river erode a rock versus the Grand Canyon forming. Same process, different timescale.
Understanding macroevolution isn’t just about satisfying our curiosity about the past. It helps us understand biodiversity, predict how organisms might respond to environmental changes, and even informs fields like medicine and conservation. Evolution is the framework that makes sense of life’s diversity, and macroevolution is what shows us how we got here.
References
- Futuyma, D. J. (2017). Evolutionary biology today and the call for an extended synthesis. Interface Focus, 7(5), 20160145. https://doi.org/10.1098/rsfs.2016.0145
- Futuyma, D. J., & Kirkpatrick, M. (2017). Evolution (4th ed.). Sinauer Associates.